Allgemeines
What has changed in the US Stock Market on 9th November 2020? – A Machine Learning View
Share article on LinkedIn
We investigate changes in market dynamics before and after 9th November 2020.
Recent advances in ML explainability enable us to compare what our machine learning models learn from data before and after 9th November 2020.
Most firm characteristics investigated show surprisingly similar behavior with notable exceptions of short-term momentum and trading volume.
Systematic investing is about understanding, monitoring, and extending models which in turn drive day-to-day portfolio decisions.
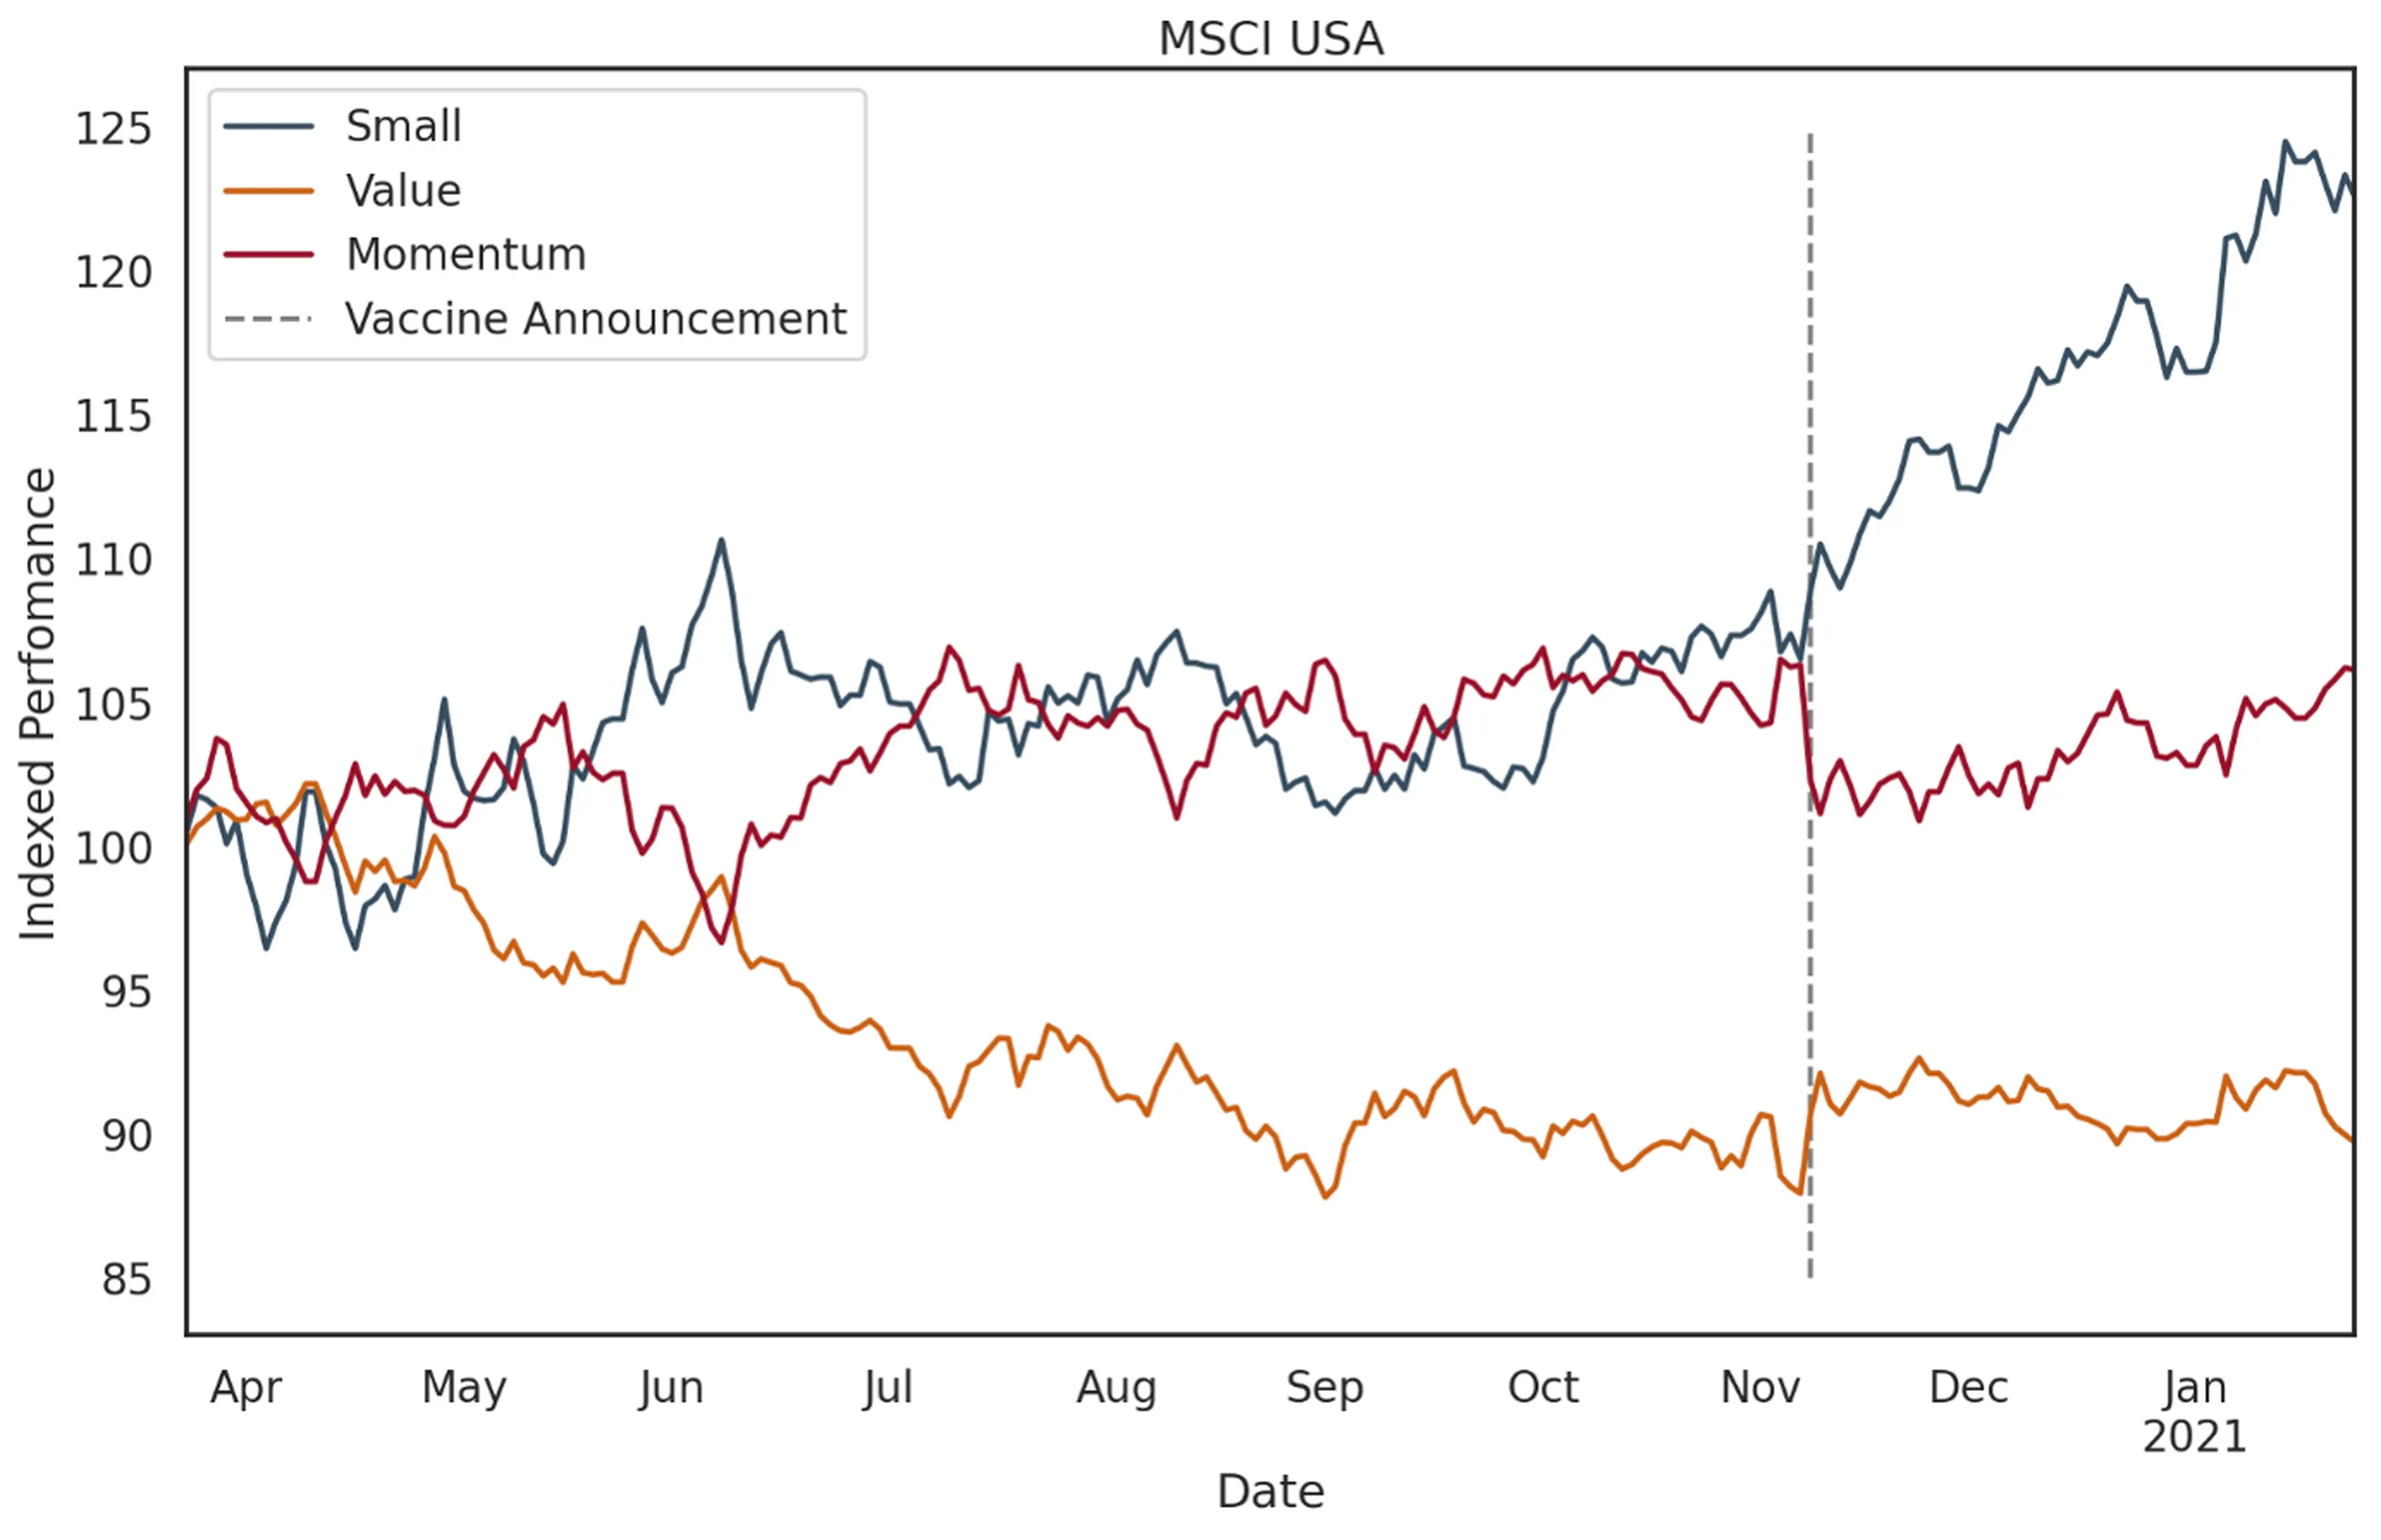
Figure 1: Cumulated performance of daily relative performance between MSCI USA Small Cap, MSCI USA Value, MSCI USA Momentum versus the MSCI USA NR. First data point: 2020-03-19. Last data point: 2021-01-25.
After rising skepticism in October about how fast an effective vaccine is going to be available, the announcement on 9 November 2020 that the Pfizer/Biontech vaccine was more than 90% effective stirred up markets. The news caused an abrupt shift out of sectors that have flourished during the pandemic, such as technology, and into beaten-down stocks such as real estate and airlines. Even though the intraday swing has been sizable, the broad stock market as measured by MSCI USA NR only moved a moderate 0.82% close-on-close. Nonetheless, the shift caused unprecedented moves in equity factors, especially value and momentum. Figure 2 exhibits how extraordinary the moves on 9 November 2020 have been. Both momentum and value factor return were extraordinary. Such a large momentum underperformance as well as value outperformance has not been observed in the previous 20 years. In Figure 1 the day of the announcement presents itself more as a single event than a starting point for another regime from a factor performance point of view. No lasting change of trends in factor returns can be observed.
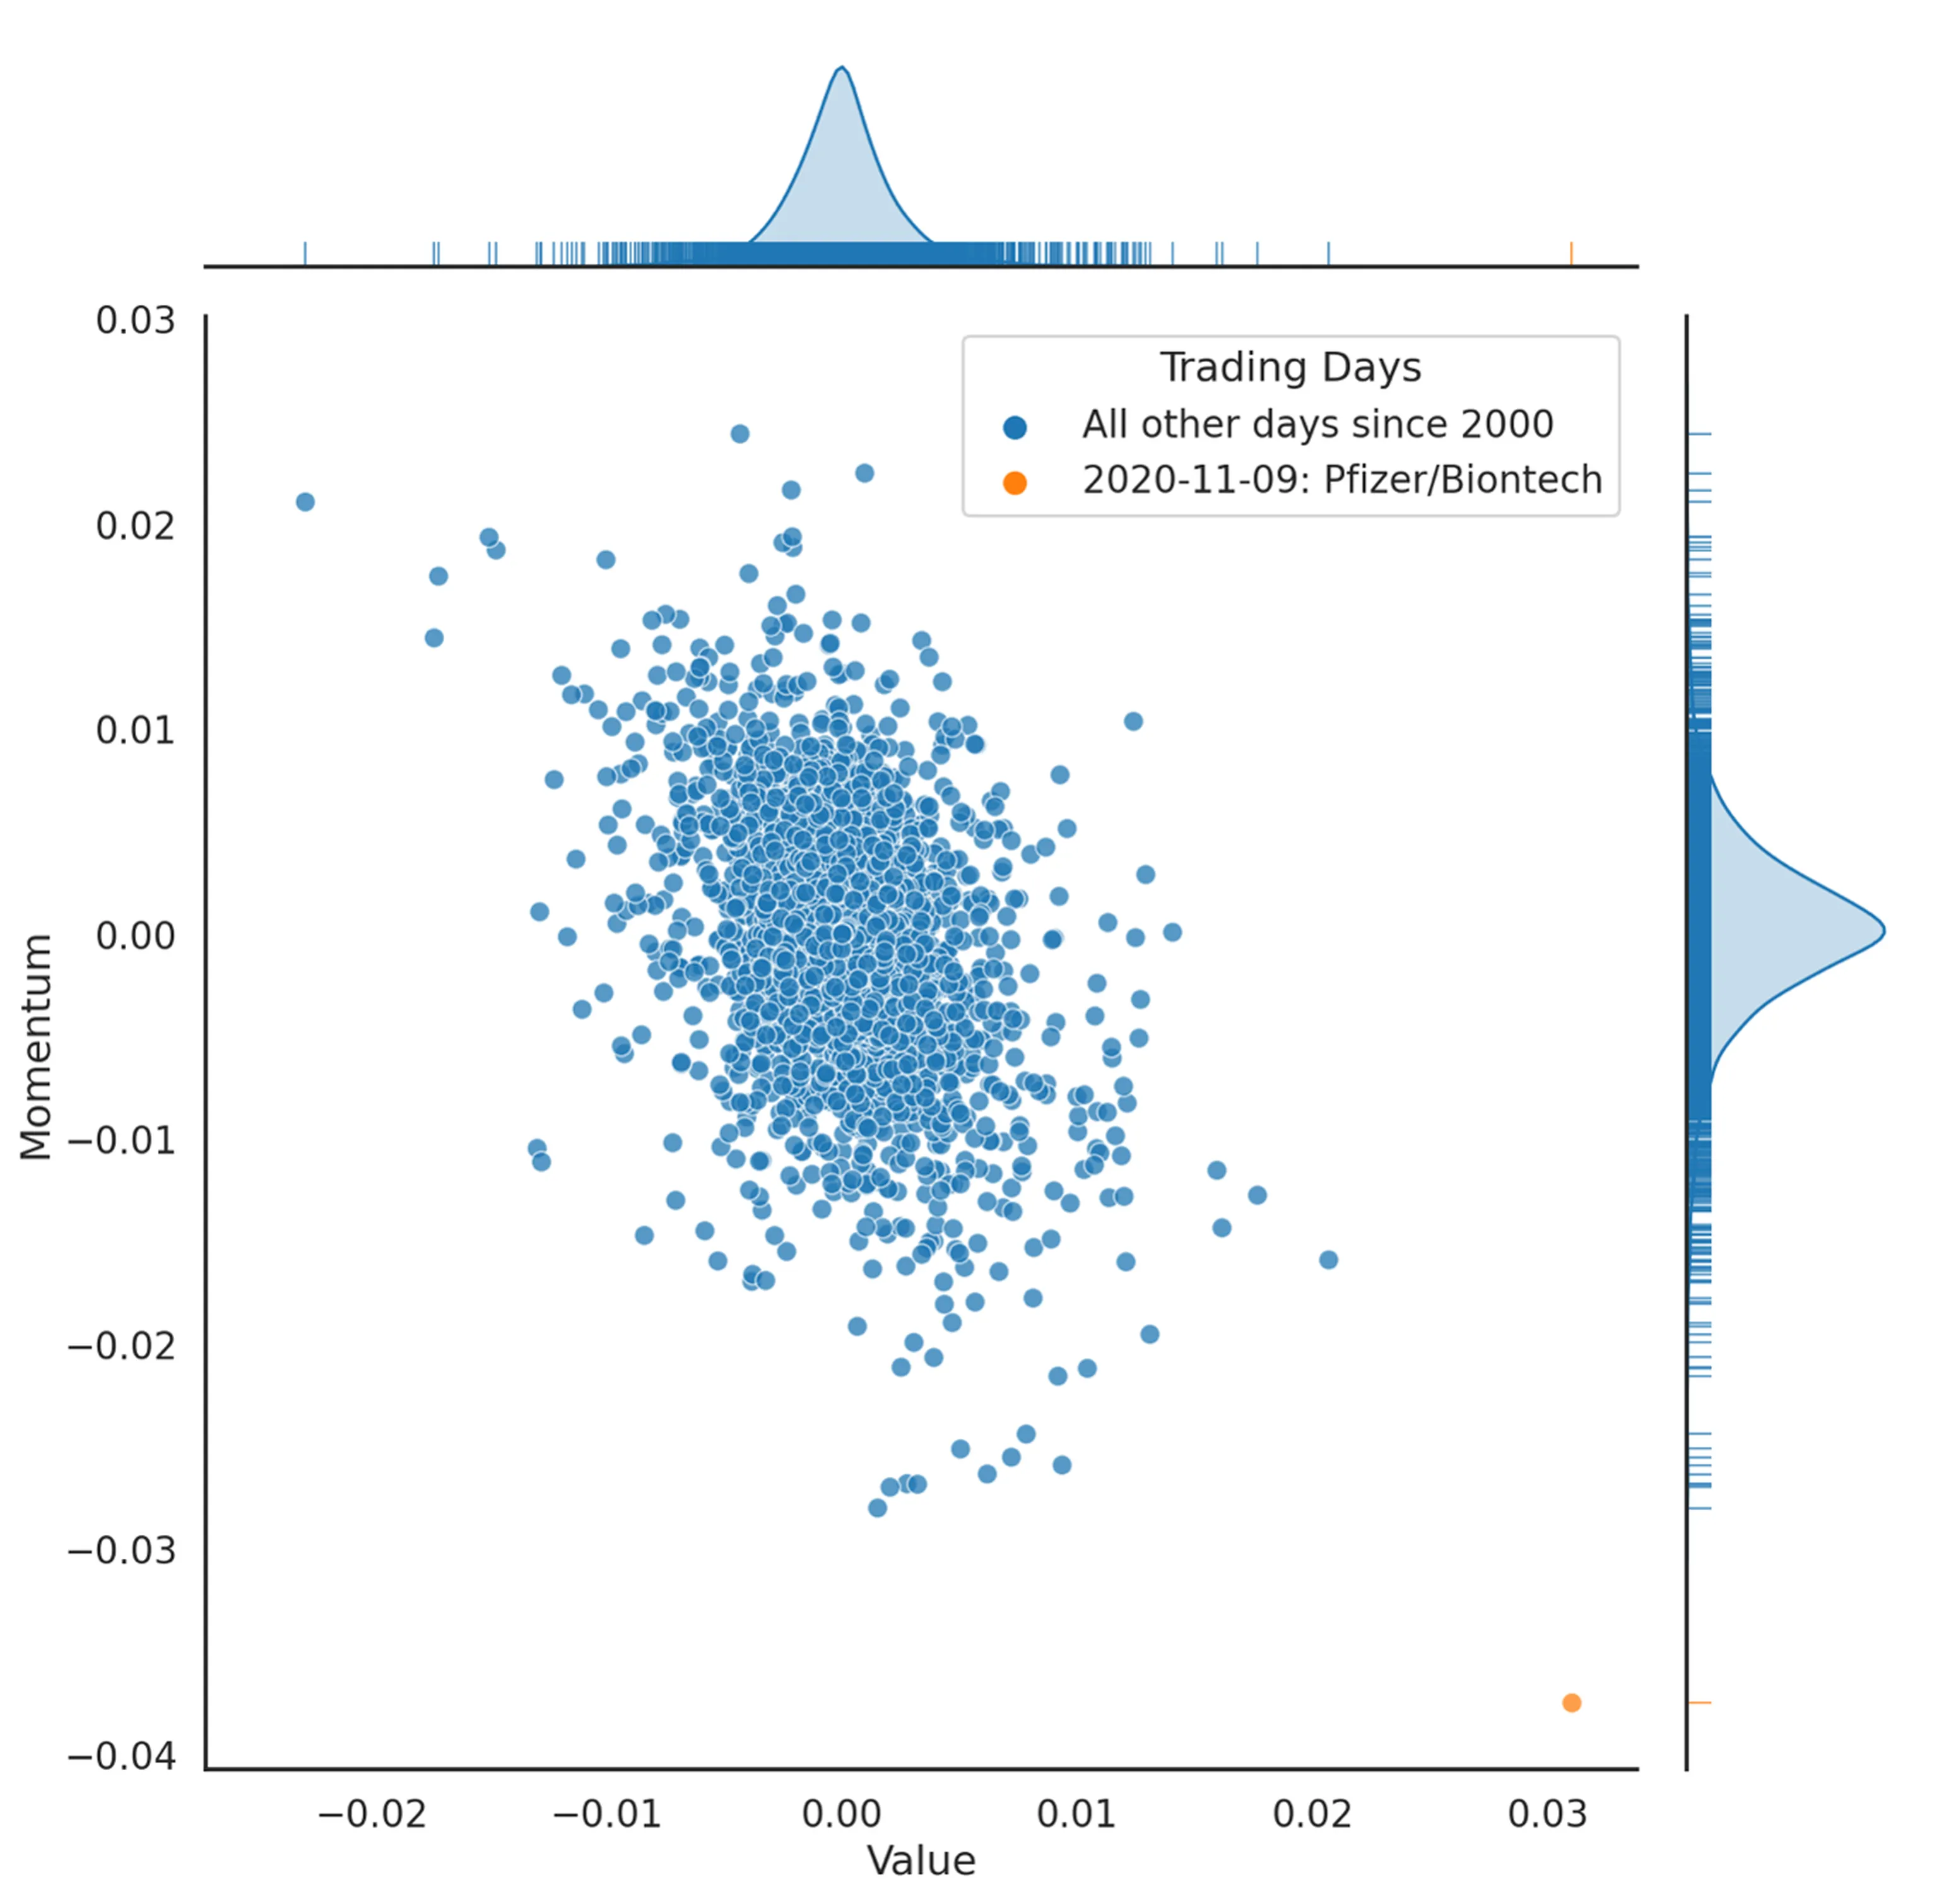
Figure 2: Daily relative performance of MSCI USA Momentum and MSCI USA Value against the MSCI USA. Daily data from 2001-01-01 to 2021-01-07.
Traditional factor investing in the equity markets seeks to explain differences in stock returns using a linear combination of firm characteristics such as value, size, quality, and momentum. In recent years, advances in machine learning have made it possible to automatically build purely data-driven non-linear models based on a variety of firm characteristics.
One challenge which has prevented wide-spread adoption of machine learning in the investment industry has been the fact that machine learning models are often hard to explain. In other words, it is often hard to get an intuitive understanding of the model behavior. Here we take advantage of recent advances in the field of explainability [Lundberg, et al. 2020] to overcome this challenge.
Besides deep neural networks, decision tree models are an important type of model in supervised machine learning. Single decision trees, if small enough, are relatively easy to understand but tend to readily overfit, i.e., they describe the training data very well but tend perform badly on new and unseen data. One way to overcome this challenge is to use many decision trees (often referred to as forest). A random forest regression model builds a diversified set of many decision trees. Each tree in the forest is trained on a slightly different subset of the data. The output of the random forest model aggregates the results of all these trees.
We train two different ML models (random forest regression to be specific). One with data during the recovery after the 2020 Q1 sell-off to before the vaccine announcement (2020-03-24 to 2020-11-06) and another one with data from 2020-11-10 to 2021-01-10. We use these two models as probes to shed light on possible changes in the market before and after the event.
In theory, one can visualize all decision trees in the random forest and follow the deterministic decision processes in every tree but in practice no human being can follow and aggregate hundreds of decision trees of a typical real-world random forest model.
We use the SHAP method described in [Lundberg, et al. 2020] to attribute how a feature or firm characteristic contributes to the model output. The SHAP method has desirable properties such as contributions are additive and consistent which help with interpreting the results.
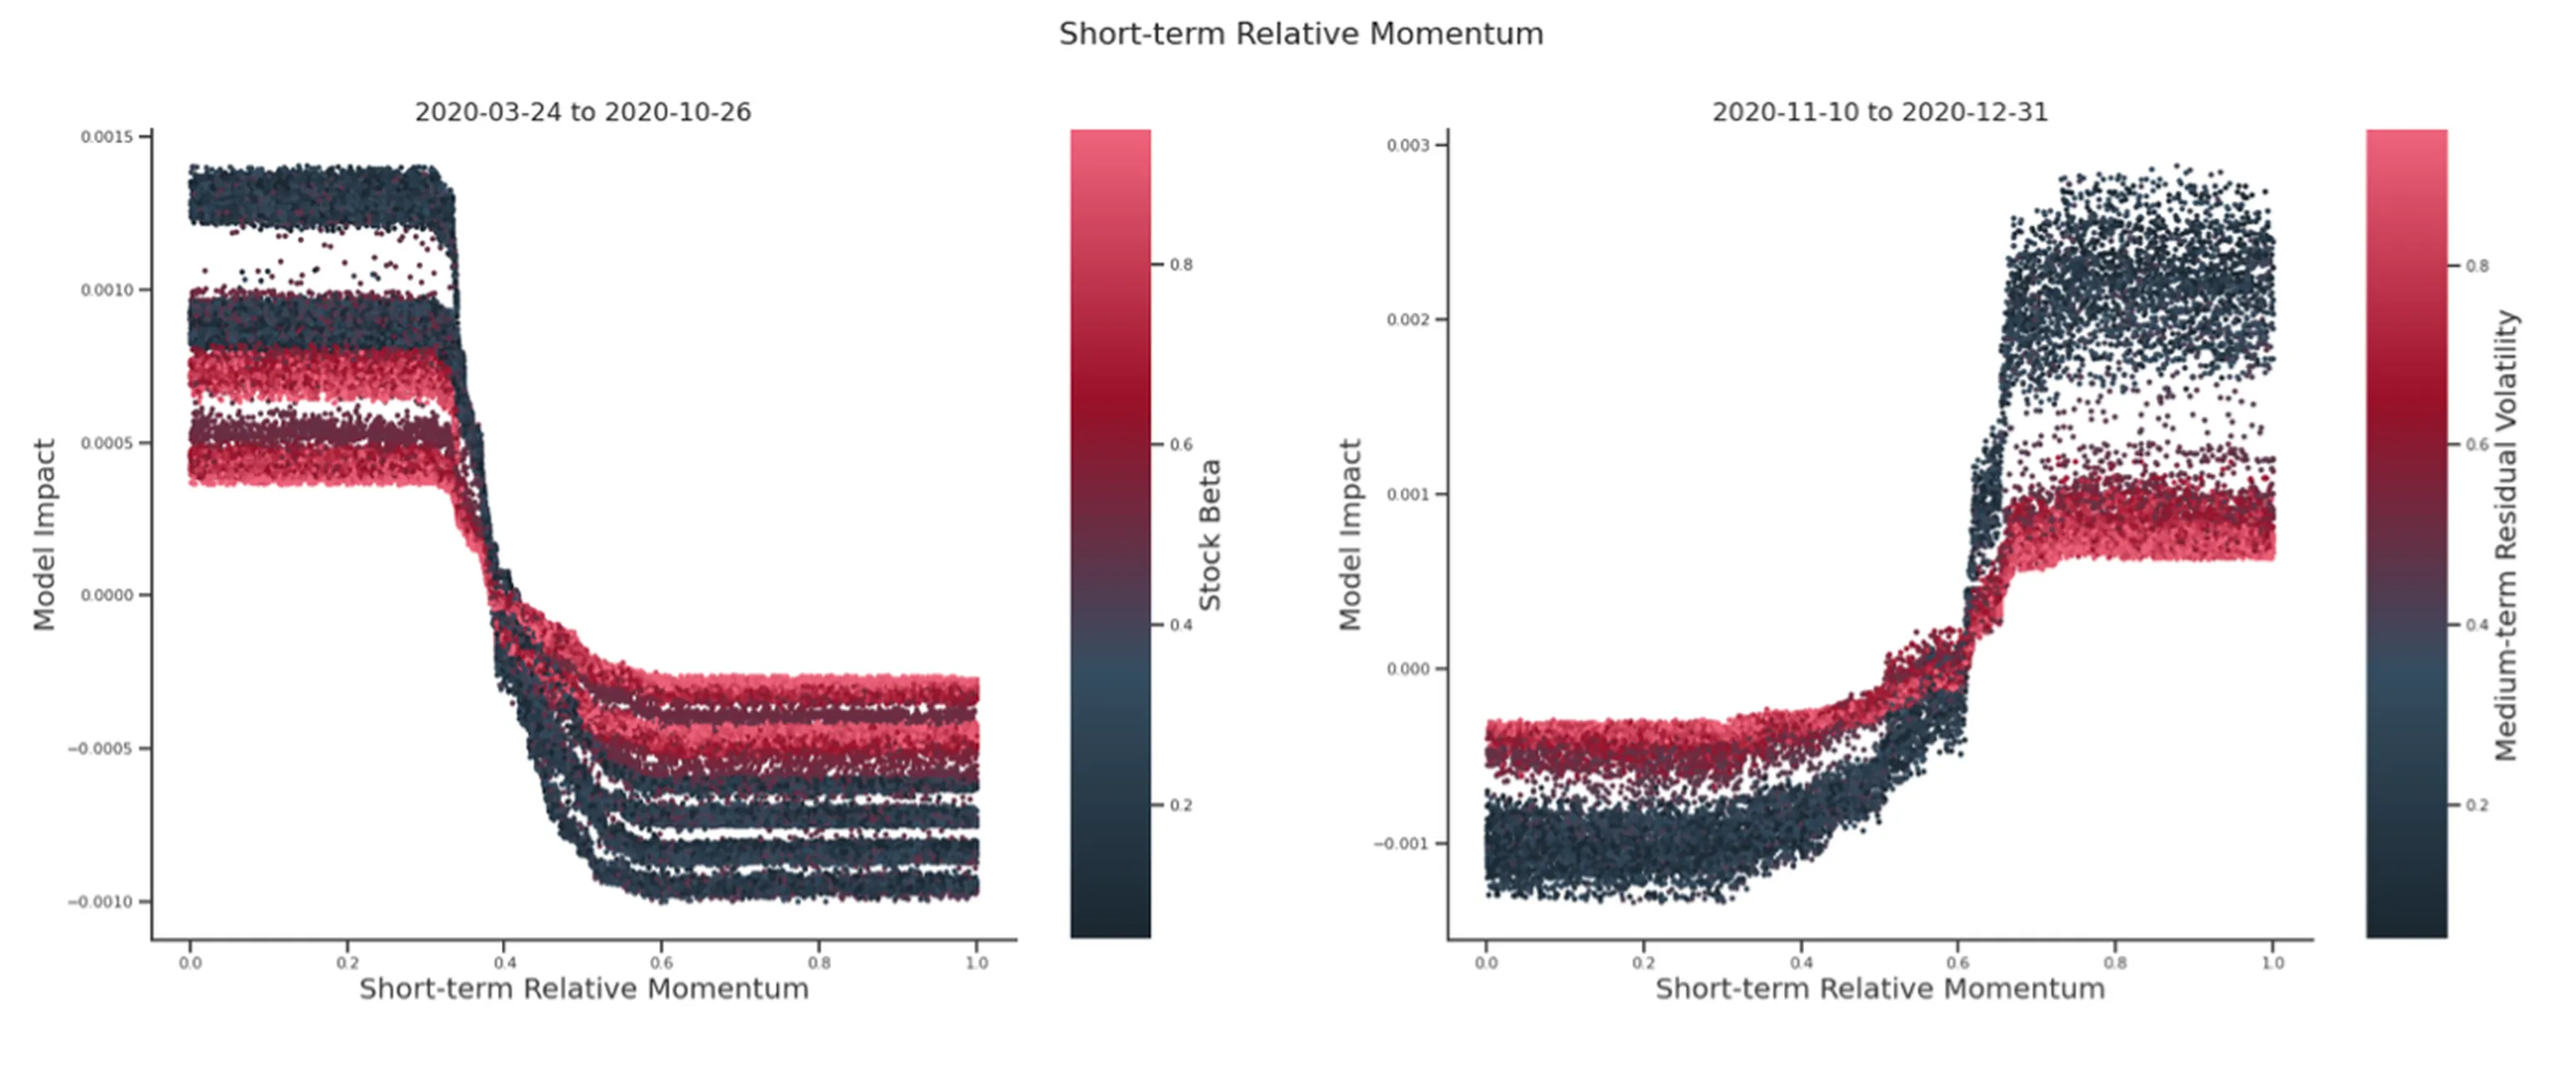
Figure 3: Influence of short-term momentum on the model.
The left side (time before the vaccine announcement) of Figure 3 shows that a low short-term relative momentum contributes positively to the predicted ranking and a high short-term relative momentum contributes negatively. In other words, it has learned “a buy the dips” strategy.
Additionally, the color coding of the dots shows that the model impact of short-term momentum is modulated by the stock beta: For high beta stocks (represented by red points) the effect of short-term momentum on the model output is lower compared to low beta stocks (represented by darker points).
Interestingly, the behavior has reversed after the announcement. Here the model has learned to chase short-term momentum and it is modulated by medium-term residual volatility, specifically, this effect is larger for stocks with low medium-term volatility (represented by darker points).
In order to maximize the future ranking of stocks in the universe models trained with data before and after the vaccine announcement favor high beta names all else equal.
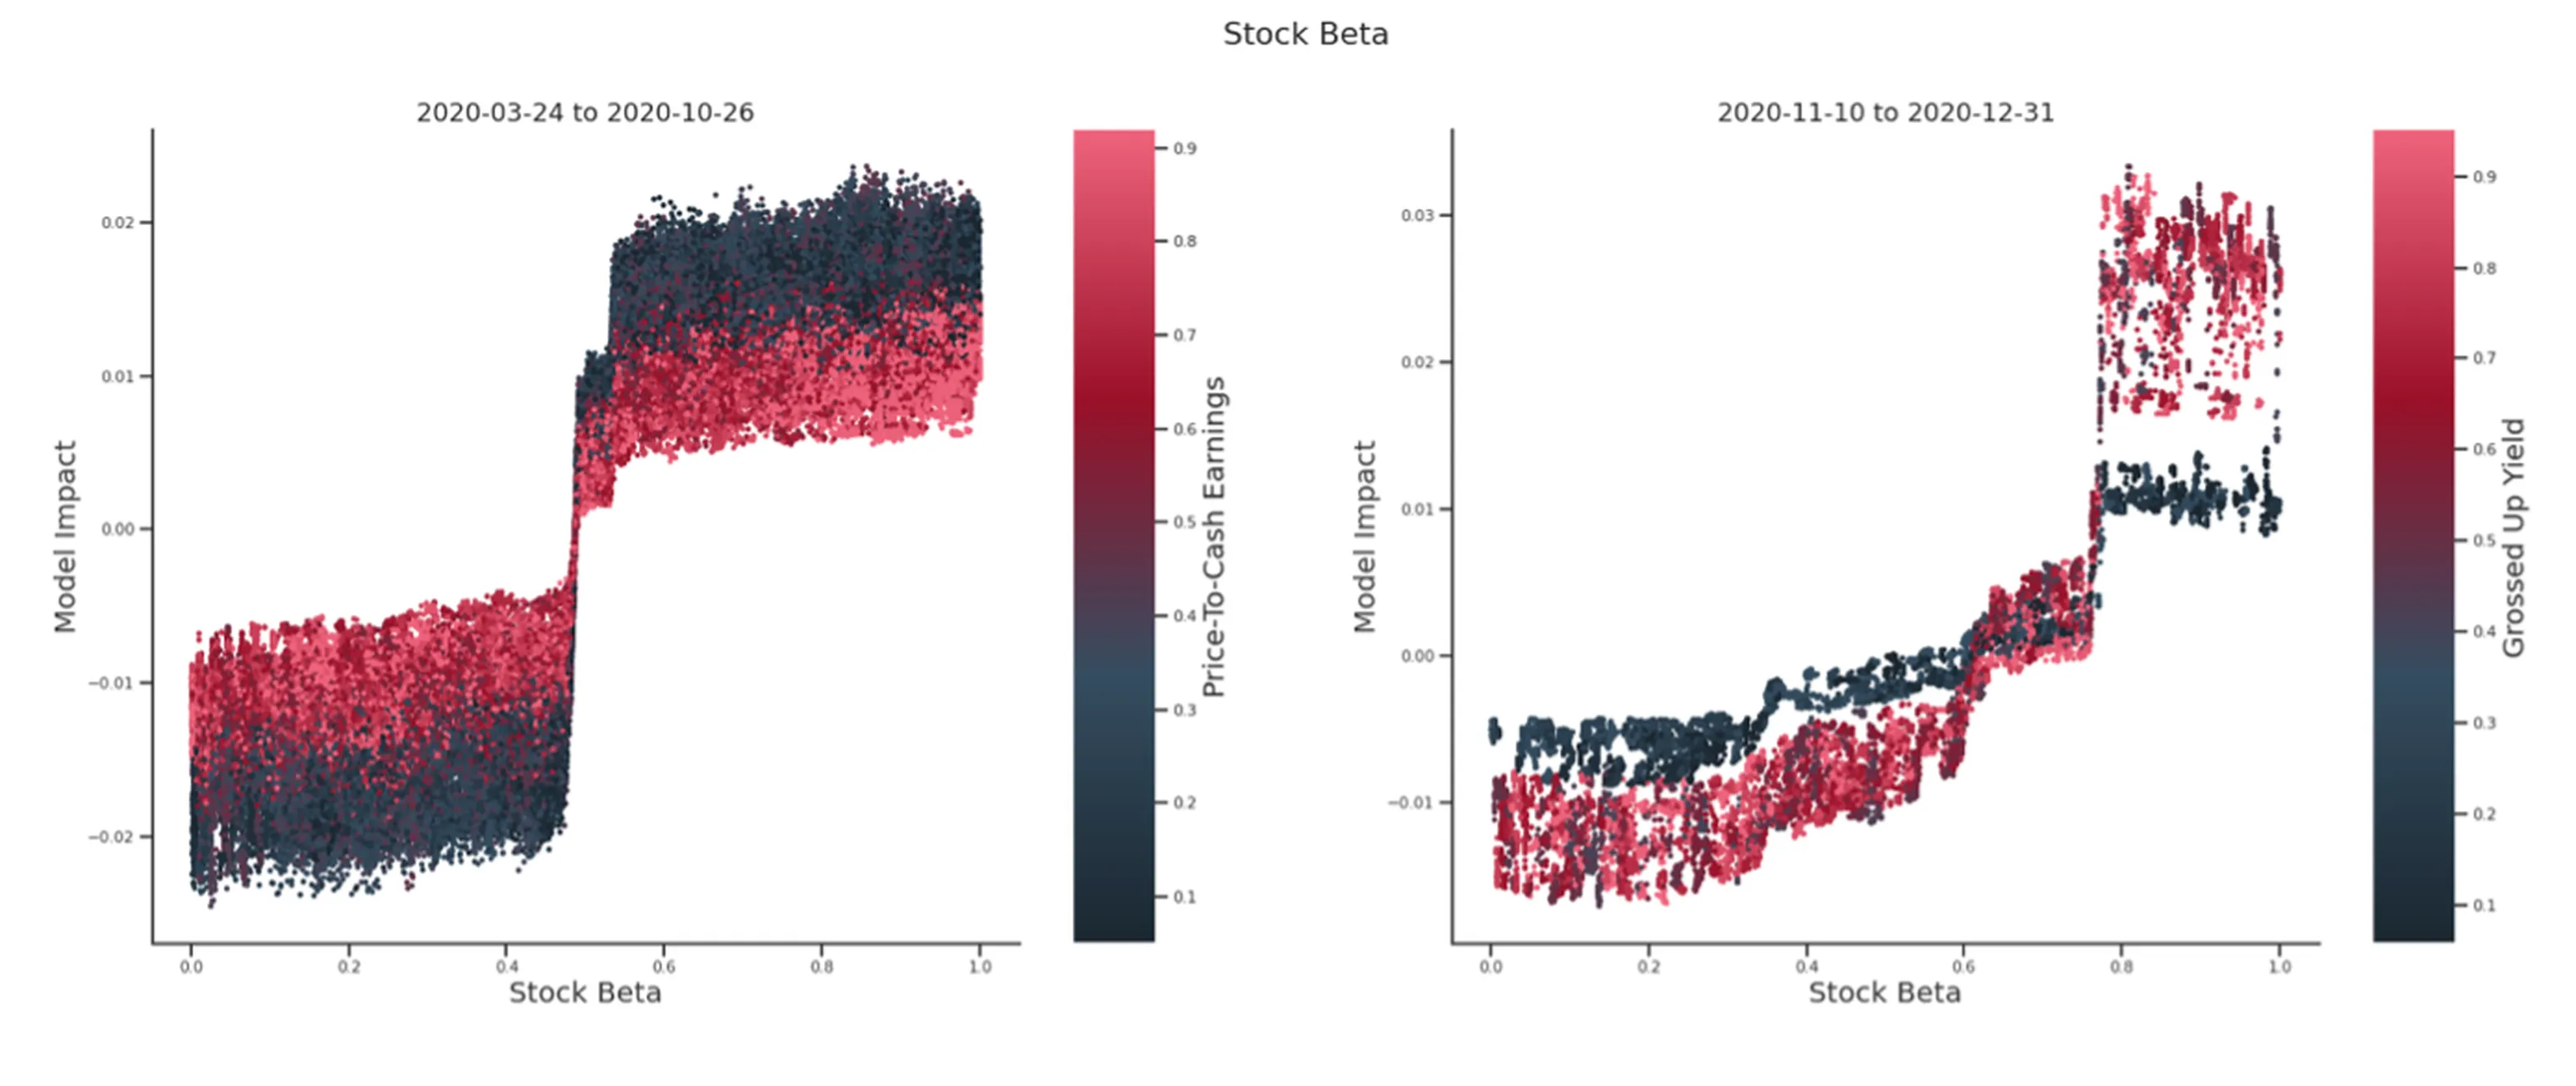
Figure 4: Influence of stock beta on the model.
Looking at dividend yield as an indicator for future stock ranking reveals a surprisingly similar structure/shape when it comes to the effect on the model. The similarity is of this relationship before and after the announcement is remarkable given that the models were trained on two distinct training data sets. Low dividend yields had a positive and high dividend had a negative impact on the model. In other words, the model learned that a stock with low dividend yield is more likely to outperform other stocks in the US large and midcap universe than a stock with a high dividend yield all else equal.
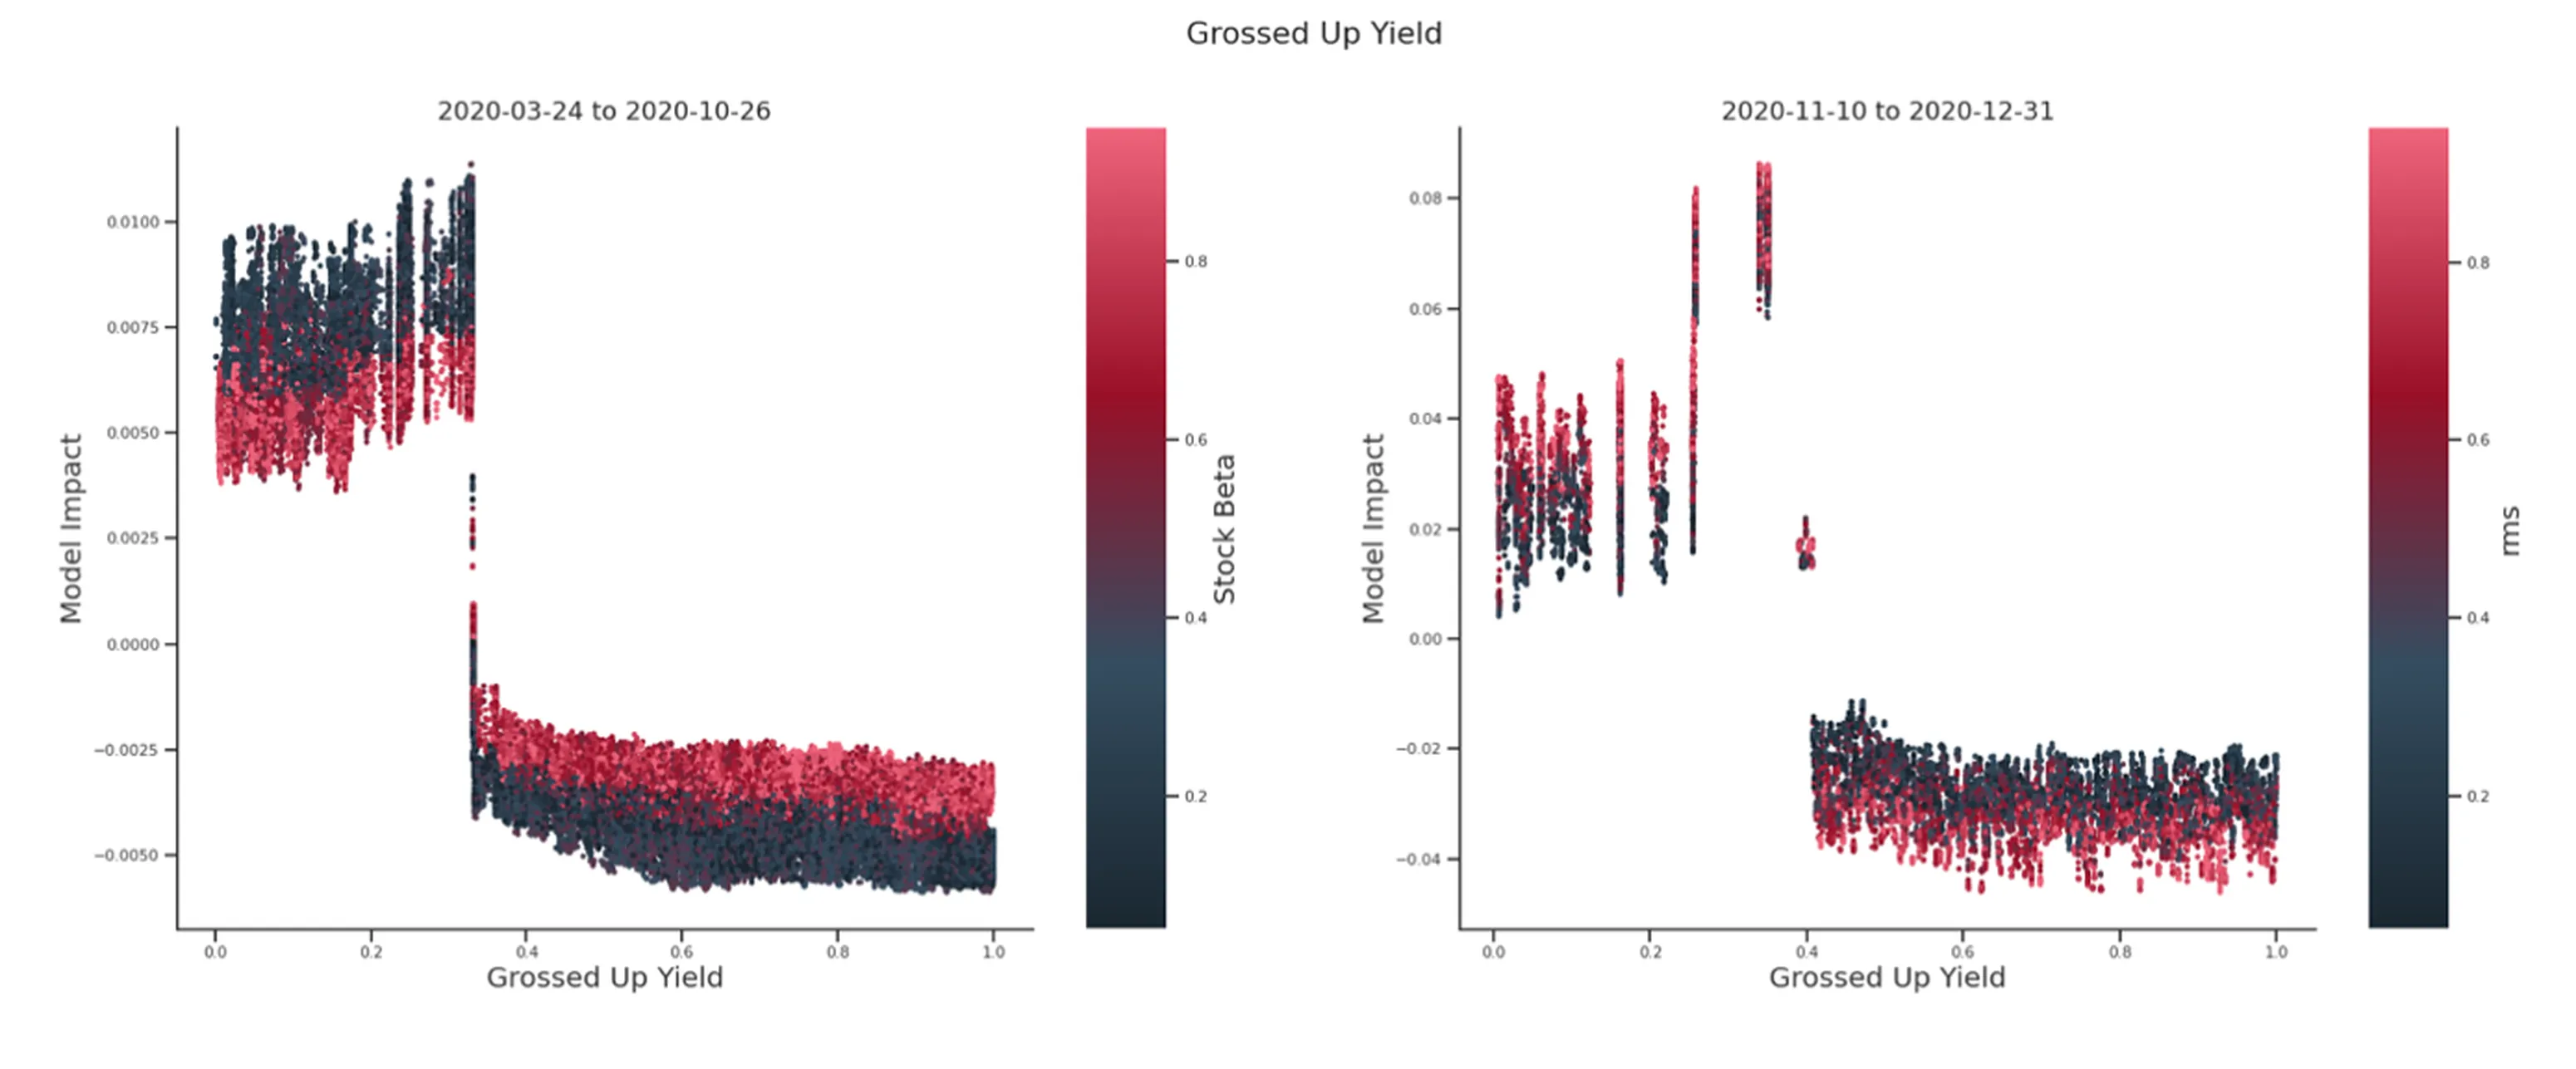
Figure 5: Influence of dividend yields on the model.
Even though small caps jumped on the day of the announcement, small caps had started to outperform before (see Figure 1). Figure 6 shows that the model correctly identifies the positive effect of a relatively small market capitalization before and after the announcement.
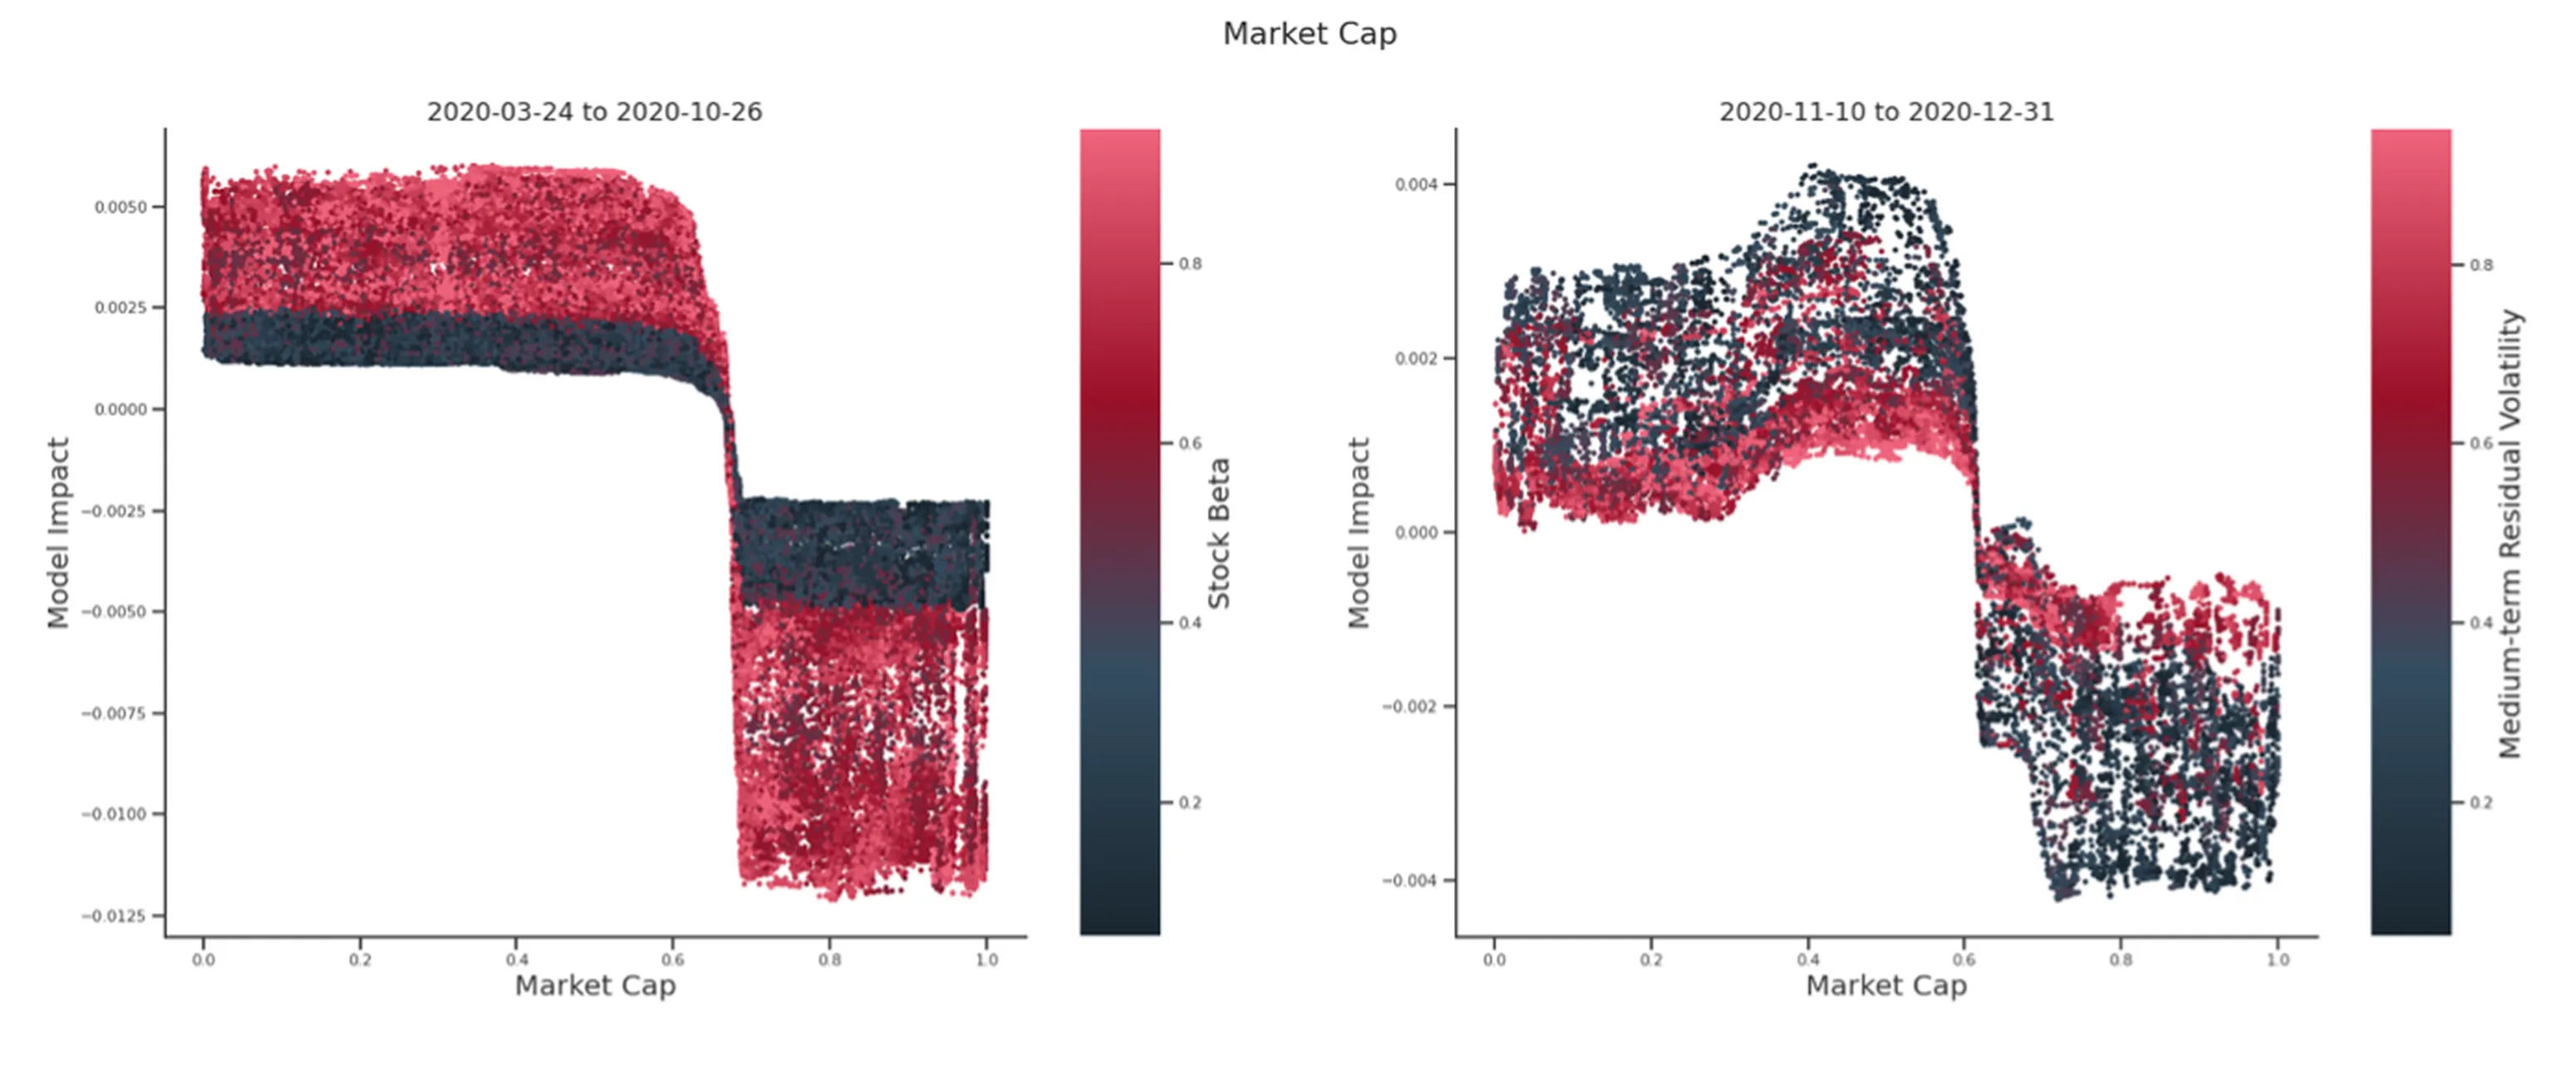
Figure 6: Influence of market capitalization on the model.
Figure 7 shows the impact of trading volume on the model. Its influence flipped from favoring low volume stocks consistent with some kind of liquidity premium to favoring stocks with relatively high volume consistent with market participants chasing returns.
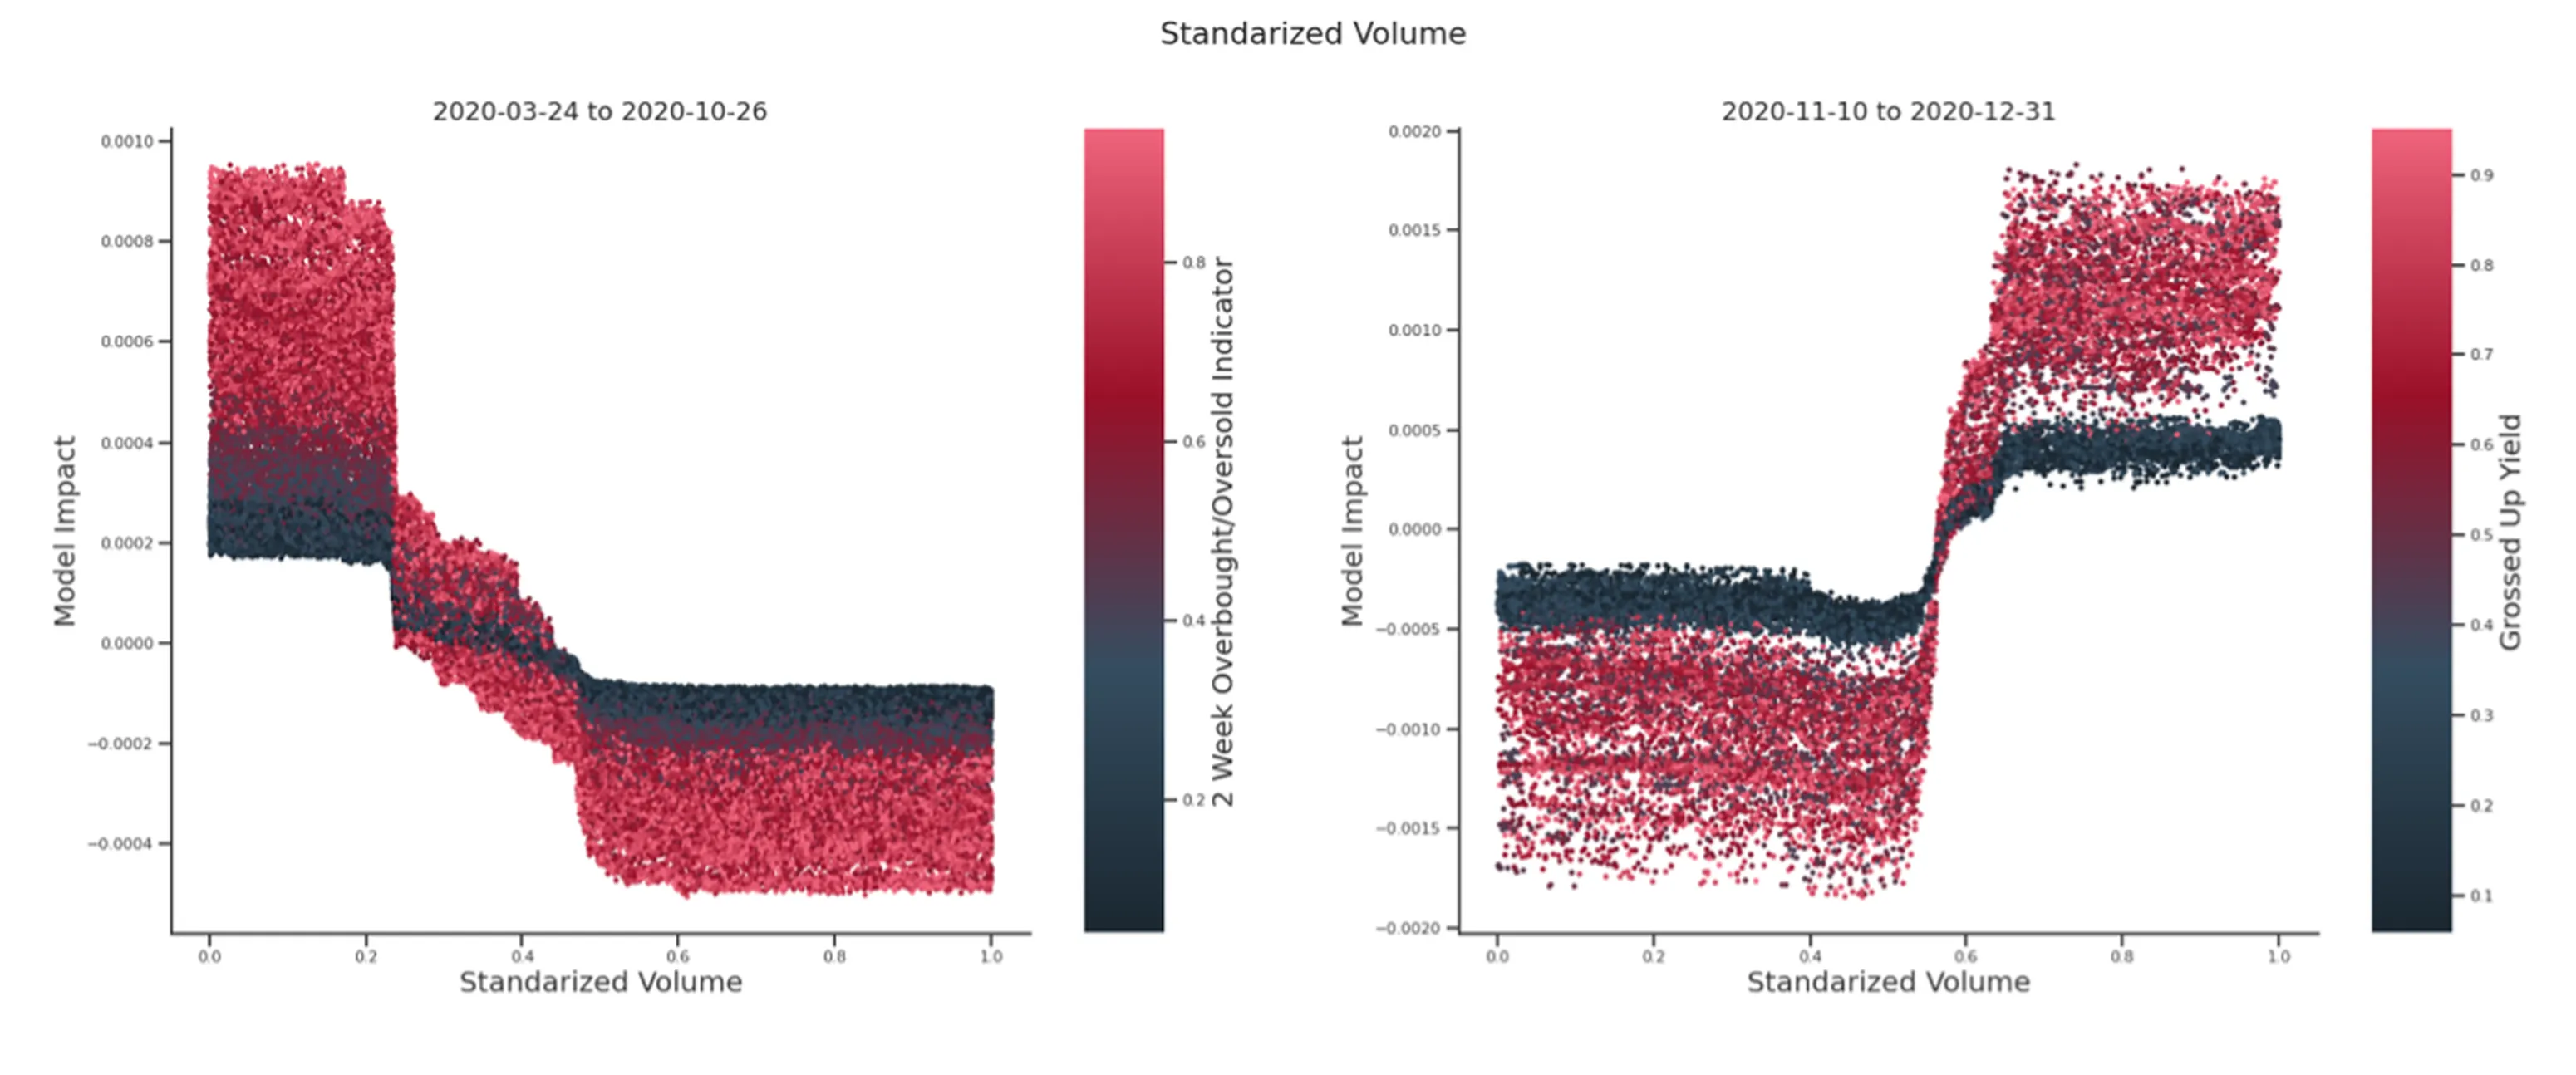
Figure 7: Influence of trading volume on the model.
On the other hand, it raises the question of how stable this 'anti liquidity premium' can be going forward as liquidity premiums are ubiquitous in financial markets.
The announcement on 9 November 2020 that the Pfizer/Biontech vaccine was more than 90% effective stirred up markets. Mainly prompted by extreme factor movements many market observers speculated about lasting changes in market dynamics.
In order to investigate this question, we trained a machine learning model on data of stocks from the MSCI USA universe before and after 9th November 2020 to predict the relative ranking of stocks in the subsequent two weeks. Using state-of-the-art machine learning explainability techniques, we showed that it is possible to uncover what the models learned and contrast the results.
Most firm characteristics investigated show surprisingly similar behavior with notable exceptions of short-term momentum and trading volume. Short-term momentum changed from buy-the-dips to chase-short-term-performance. The impact of trading volume on the model also flipped from favoring low volume stocks consistent with some kind of liquidity premium to favoring stocks with relatively high volume consistent with market participants chasing returns.
Using non-linear data-driven machine learning methods to build stock selection models can be seen as a natural extension of linear factor models. The fact that the explained model behavior is consistent with observed factor returns is further validation of this approach.
Being able to comprehensively investigate and explain machine learning models eliminates a major obstacle for adopting machine learning models as a powerful tool in investment management. Systematic investing for us means that the portfolio manager does not make discretionary changes to portfolios, but monitoring, understanding, and extending models to make sure that they remain relevant is essential. This means that there is a middle ground between blindly following the representative investor using passive investment vehicles and a portfolio manager making discretionary portfolio decisions.
Interested? – Contact us at funds@sgvaluepartners.ch
Shapley, L. S. A value for n-person games. Contrib. Theor. Games 2, 307–317 (1953).
Lundberg, S.M., Erion, G., Chen, H. et al. From local explanations to global understanding with explainable AI for trees. Nat Mach Intell 2, 56–67 (2020).